Qwen3.8 Inference
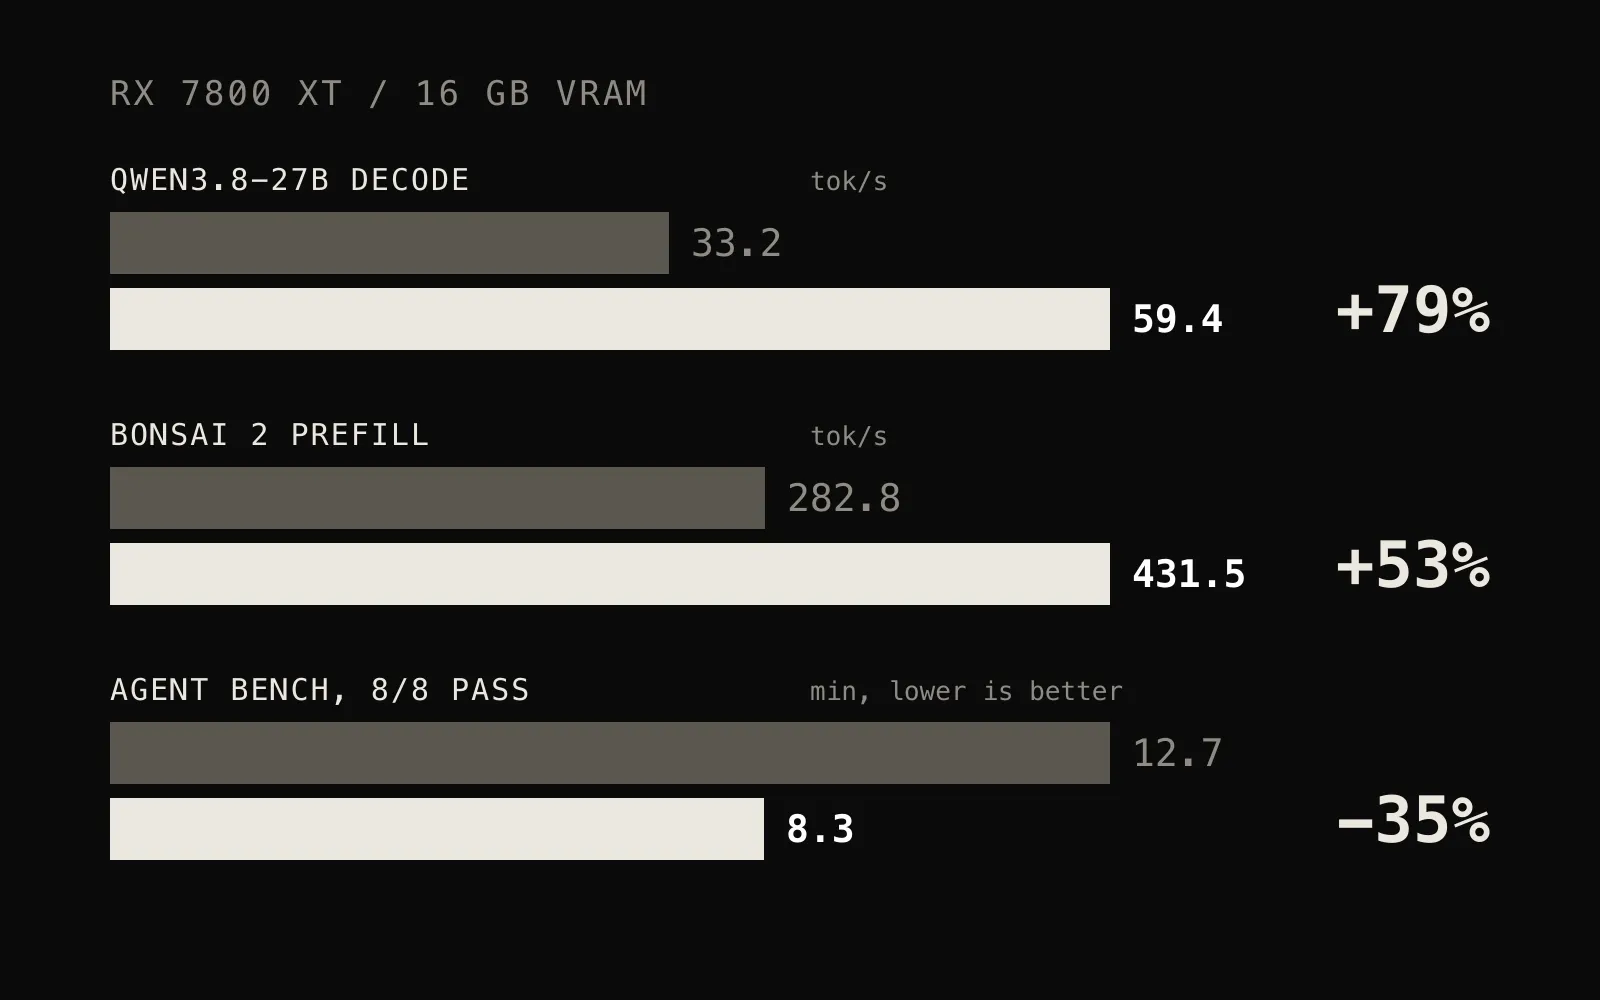
Runs a 27B LLM entirely in 16 GB of VRAM on a consumer AMD GPU and tunes it to drive a coding agent: speculative decoding took decode from 33 to 59 tokens/s, and custom HIP kernels sped up ternary-model prefill by 53%. Every change is backed by checked-in benchmarks.